LLM web-design coding tests
LLM web design test: twelve models, four identical briefs
Four briefs.
Every model got the same one.
Twelve language models received the same four web-design briefs. Same copy, same constraints, one self-contained HTML file each: no external libraries, no follow-up prompts, first output kept. The only variable is the model. Everything else — the brief, the words, the technical rules — is fixed. This page is the evidence: browse all 33 submissions, read the prompts, and compare sites side by side. For the ranked verdict, see how the models ranked.
4 briefs12 models33 pages1 HTML file each
The boardclick a cell to open · click a name for the whole row or column
How the test works
Each model was given the full brief as a single prompt: context, fixed copy, functional requirements, technical requirements, and an instruction to return only the HTML file. No design system, no font list, no per-model tuning. Default reasoning settings. One generation per cell.
The constraints that applied to every brief:
- One HTML file that opens correctly from disk, CSS and JavaScript inline.
- Vanilla HTML, CSS and JavaScript. No libraries, no CDNs, no icon packs.
- Copy used verbatim — no invented sections, no rewritten headlines.
- No follow-up prompts. The first complete file is the submission.
A full grid of 12 models × 4 briefs would be 48 sites. This corpus has 33. 7 models completed every brief: Claude Opus 5, Grok 4.6, GPT-5.6 Sol, Qwen3.8-Max, DeepSeek V4 Flash, GPT-5.6 Luna, Muse Spark 1.3.
The rest of the field is incomplete on purpose, not because a model refused the task. DeepSeek V4 Pro, Kimi K3 and MiniMax M3 were run on Still Running only — those are models that were available for one sitting rather than a full-time subscription. Claude Fable 5.1 and GPT-6 Astra shipped after the original four-brief run and were added on Pip & Pocket. Empty cells are briefs that were not run.
A submission is a complete HTML file. The one exception is Opus 5 on Ordinary Hours, which also shipped three hero images referenced from that file. Nothing here is a multi-turn repair, a cherry-picked rerun, or a hidden system prompt on top of the published brief.
The four briefs
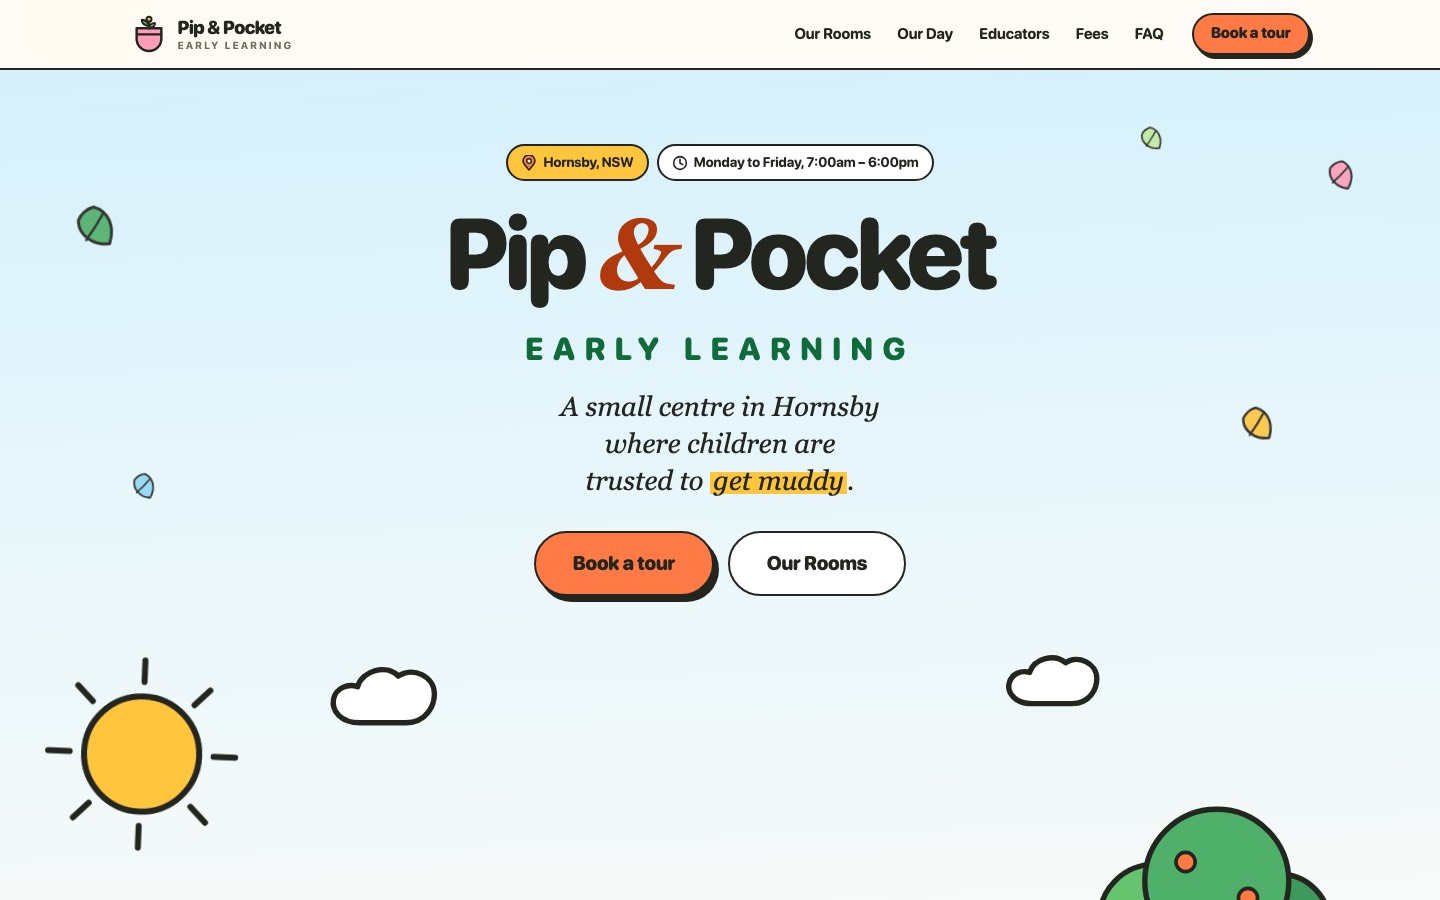
01 / Early learning centre
A 49-place childcare centre that has to feel joyful and competent at the same time.
A tired parent on their phone at 7am needs to trust this place with a two-year-old. Sites like this usually fail on one side or the other — clinical and grey, or so sugary that nothing looks credible. Holding both is the design problem.
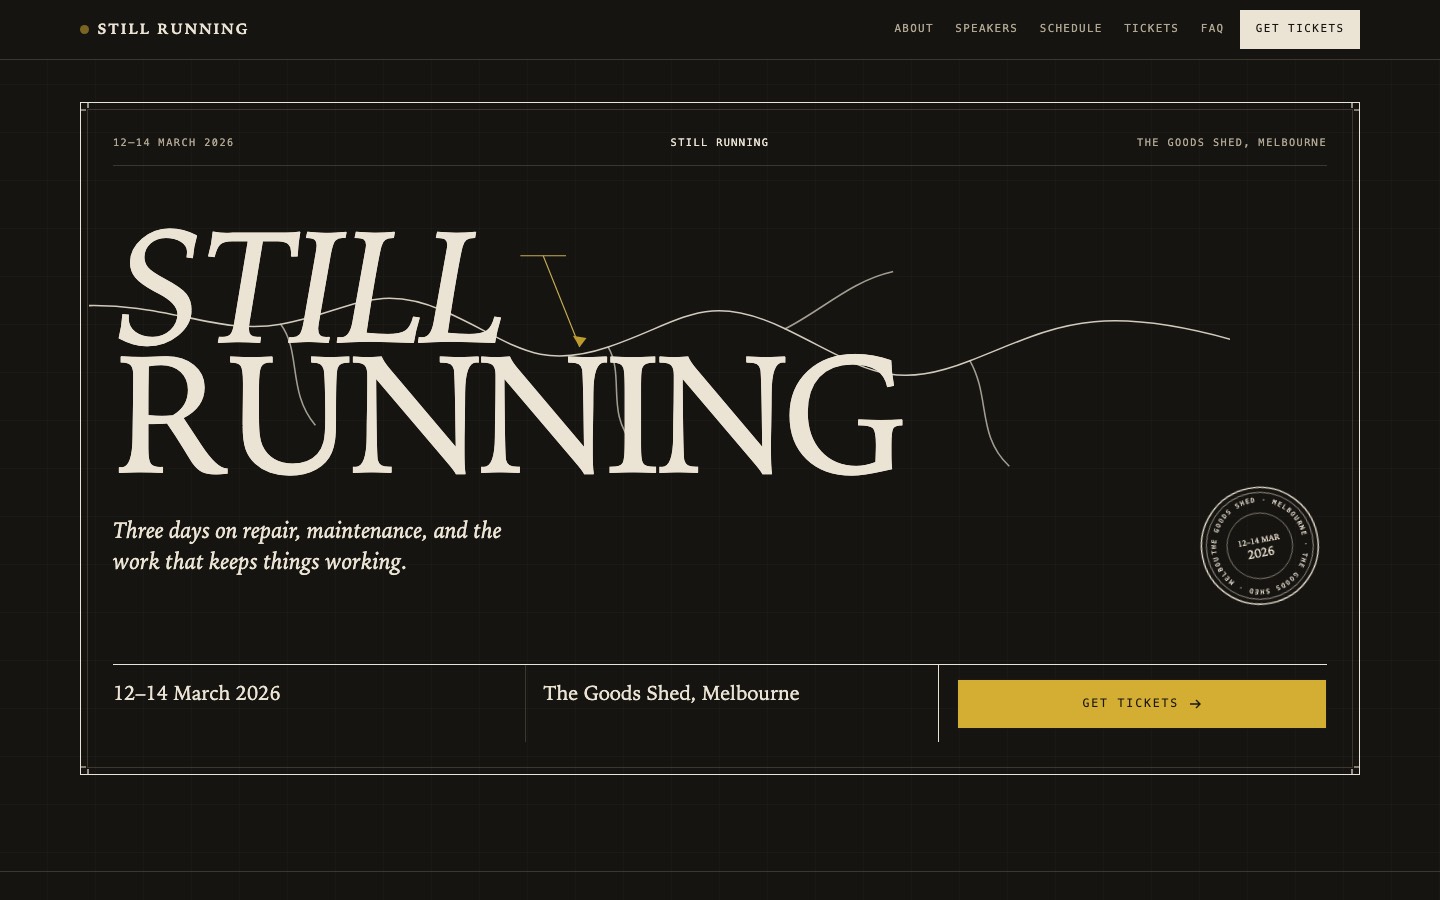
02 / Conference microsite
Three days on repair, maintenance, and the work that keeps things working.
Anyone can make a design conference look designed. The question is whether you can build a visual language for bridge inspectors, night-shift mechanics and hospital biomedical engineers that is beautiful, specific, and true to the subject.
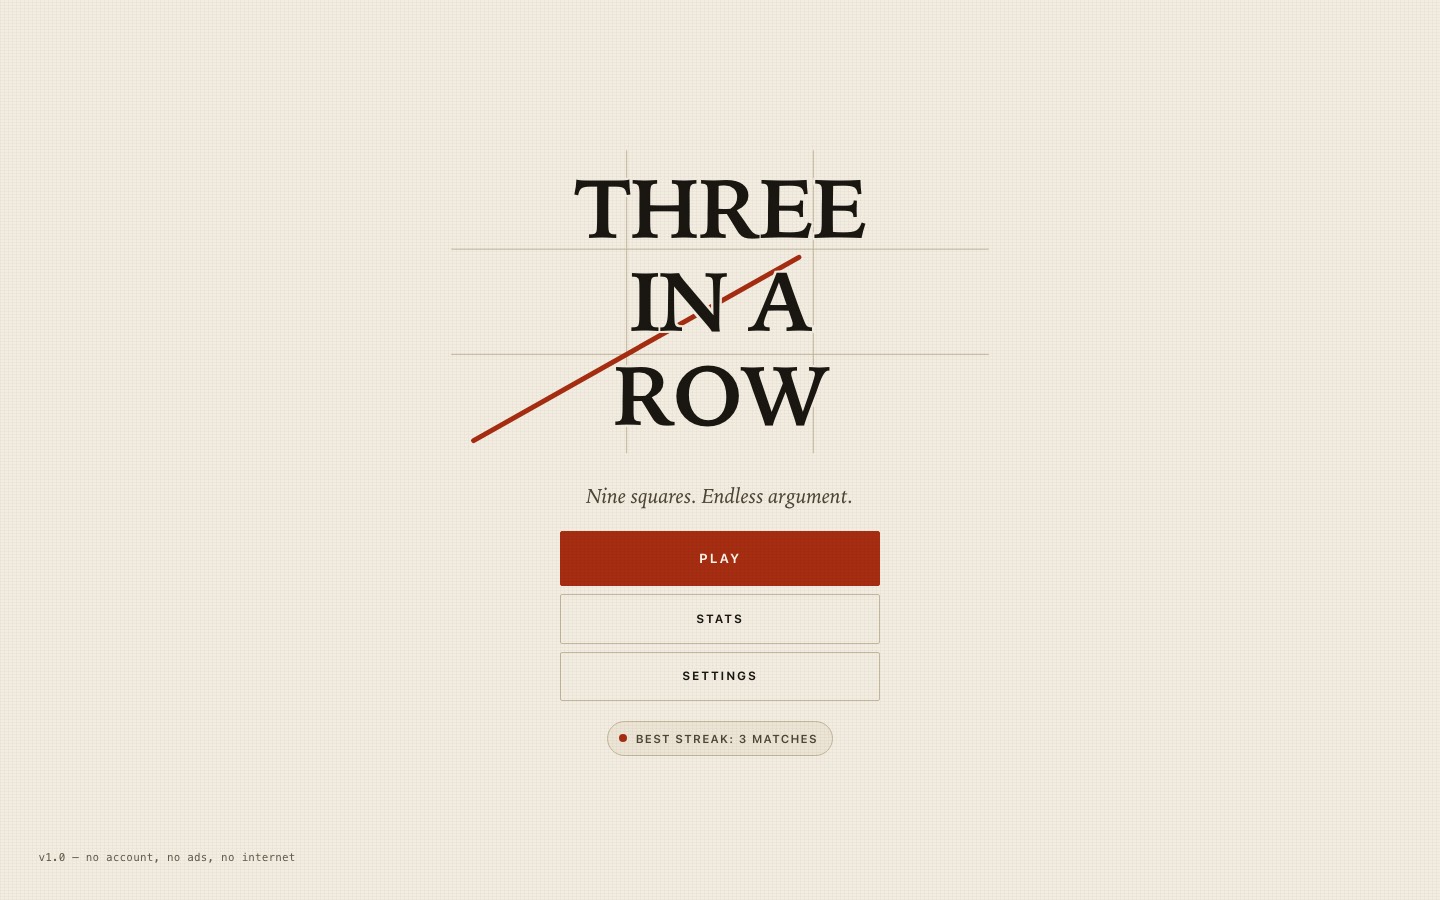
03 / Game interface
Tic-tac-toe as a real product. The logic is trivial. The interface is the work.
Most game UIs are judged on the fifty seconds a player spends in menus, not the ten they spend playing. Seven screens, three palettes, three marker sets, and a computer that can actually be impossible.
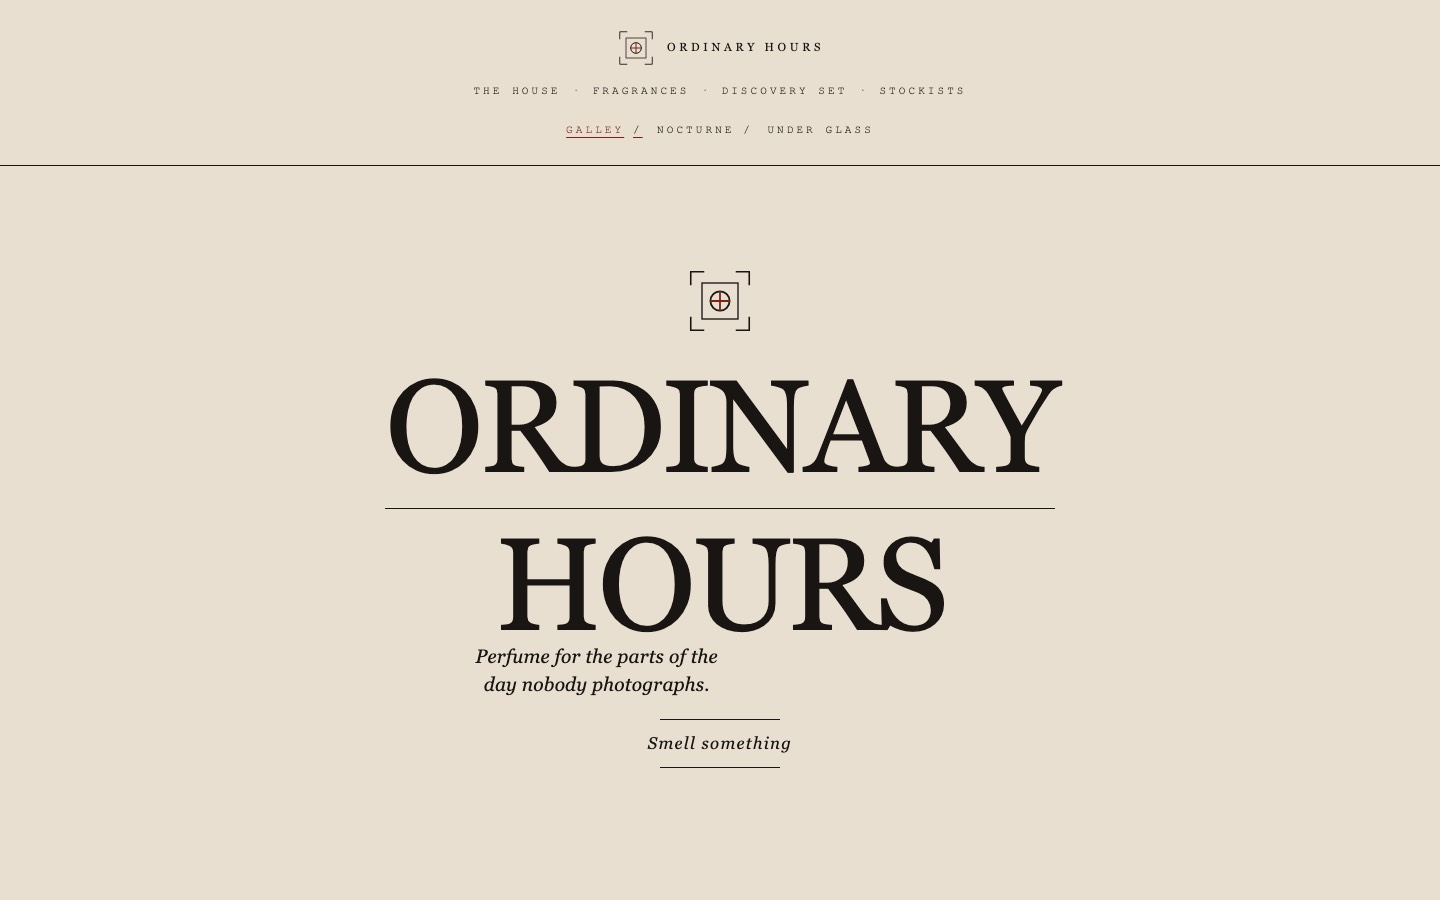
04 / Perfume house
Three complete visual identities in one file. Same copy. Three design languages.
Anyone can produce one good-looking page. This brief asks whether you have more than one aesthetic in you — three genuinely different identities, each internally coherent, switched live from a single root attribute.
The models tested
Official names, labs, and release dates. Each row links to the model’s page on this site and to the vendor’s own page.
Incomplete rows: DeepSeek V4 Pro (1), Kimi K3 (1), MiniMax M3 (1), Claude Fable 5.1 (1), GPT-6 Astra (1).
How this differs from the arenas
Design Arena and WebDev Arena run blind head-to-heads. A crowd votes, identities stay hidden, and an Elo rating moves. That answers a useful question: what does average preference look like across thousands of prompts.
This is a different question. Four fixed briefs, published prompts, full source available, one judge, no voting. You can read the brief, open the file, and disagree. The arenas are a leaderboard. This is a corpus.
FAQ
Which LLM is best for frontend development?
There is no single winner that holds across every brief. GPT-5.6 Sol, Claude Opus 5 and Qwen3.8-Max each took at least one of the four tests, and the gaps were small enough that a different judge would produce a different table. The ranked write-up is in the full ranked comparison. This site is the evidence: the prompts, the constraints, and every HTML file.
How were the models prompted?
Each model received the full brief as a single prompt: context, fixed copy, functional requirements, technical requirements, and an instruction to return only the HTML file. No design system, no font list, no per-model tuning, no follow-up. Default reasoning settings. First output kept. Open any brief and use Prompt to read the exact text.
Can I see the source code for each submission?
Yes. Every submission is a self-contained HTML file. Open a cell on the board to view it live, or use the Raw link on a submission page to read the source. The original prompts sit on each brief page.
Why single-file HTML with no libraries?
A single HTML file with vanilla CSS and JavaScript isolates design and front-end craft from the rest of the stack. No component library, no build step, no follow-up to fix imports. What you see is what the model produced in one pass, which is the thing this test is actually measuring.
Keys
/ jump anywhere←→ switch modelsP read the promptC compare⇧ click a model to compare